
-
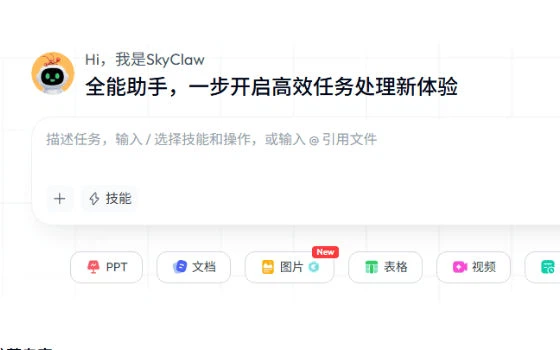
Tiangong grew from an AI search box into a task-taking agent workspace
Search is now one entry in a wider workspace: an all-round assistant takes a described task, picks skills or experts to run it, schedules it, and can be wired into a chat tool so the work happens unattended.
-
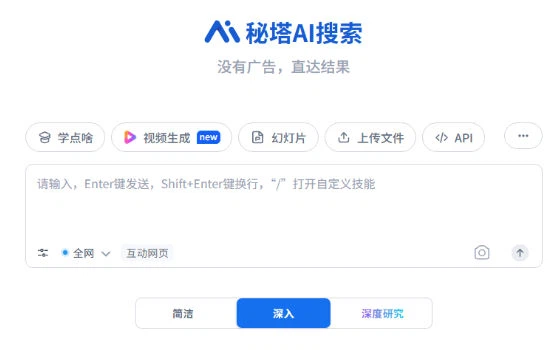
Metaso answers a query with a cited outline instead of a page of links
No ads, straight to the result: pick one of three depths, search across the web, a document library, academia, images, video or podcasts, and get an answer broken into sections with a source marker on every claim.
-
NotebookLM answers only from your own sources, then turns them into a podcast
Upload PDFs, sites, videos or audio, and every answer stays inside that material with an in-text citation you can click back to. The same sources can be reworked into a study guide, a briefing, a mind map or a two-host audio discussion.
-
LocalAI: engines pulled on demand, a model running without a card
One binary and one compatible endpoint: point the client at it and the code does not move while the model comes home. Engines arrive only when a model needs them, every feature has a path that runs on the processor, and a second machine becomes more capacity.
-
vLLM: serving a model by managing video memory like an operating system
Cutting the key-value cache into blocks instead of reserving it whole lifts memory use from three or four tenths to above nine, and the same card then serves two to four times as many requests - which is the difference between a demo and a service.
-
Msty: local and hosted models in a single window
Two engines inside one window run an open model after a click, more than 12 hosted providers can be added with your own key, and a conversation may change models halfway through - or split into panes and answer the same question twice.
-
AnythingLLM: a private AI workbench that stays on the desktop
Drag PDFs, word-processor files and tables into a workspace and you get an assistant that has read everything you own, with a citation under every answer - and the model, the vector store and the storage all live on the machine by default.
-
llama.cpp: the engine that runs a model on a bare processor
Written in plain C with no dependencies, it set the file format that made quantised models small enough for ordinary laptops, and it is the layer several familiar desktop tools quietly build on.
-
GPT4All: a local model on a computer without a graphics card
No discrete card, no account, no command line: a quantised open model runs on an ordinary processor, and a folder of your own paperwork becomes a question-answering collection that never leaves the machine.
-
Jan: a local assistant whose source you can actually read
Every line of the chat window, the model manager and the local server is published under a permissive licence, so the conversation can run with the cable pulled and nobody has to take the privacy claim on faith.
-
LM Studio: local models handled like a hosted assistant
No terminal, no parameters to mistype: a browser window lists models by size and by whether they fit your card, one click downloads, and the chat box behaves like the hosted assistants while the conversation never leaves the machine.
-
Ollama: one command puts an open model inside your working day
A runtime rather than a chat application: one command pulls and runs an open model, a local endpoint speaks the common request format, and any script or editor plugin you already have can point at it without touching the outside network.
-
NextChat: a five-megabyte client that holds every model you pay for
A client of roughly five megabytes puts the models you already pay for into one window, keeps every conversation in the browser, runs on six platforms, and charges nothing itself because the bill goes straight to the provider.
-
LibreChat: one self-hosted chat layer turns model bills into metered usage
Free software you run yourself: one window for several model providers, agents assembled without code, a sandboxed interpreter and MCP connectors, with cost per team member visible instead of dissolving into a fixed subscription.
-
Yuanbao on the desktop: select a line and it appears, WeChat files go straight in
One product, two engines, swapped from a selector at the top of the conversation without leaving the session. Files and articles arriving through the messenger are read directly, and selecting any text on screen brings the panel to the cursor instead of asking you to change windows.
-
第 1 / 2 页