
-
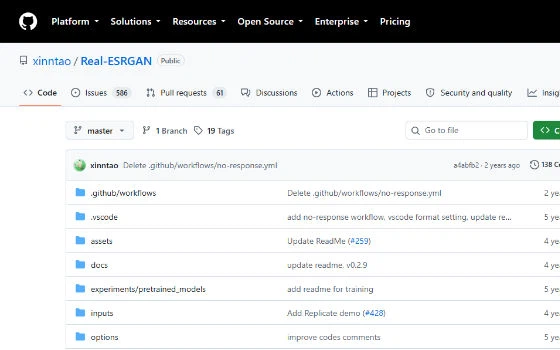
Real-ESRGAN review: the algorithm underneath a shelf of enlargement apps
Not an application but a paper and its reference implementation, trained purely on synthetic degradations and loosely licensed enough that a whole shelf of GUI products wraps it. Three ways in, with different costs.
-
Kolors writes Chinese characters correctly and opens code and weights
A text-to-image model that draws Chinese hanzi correctly instead of producing gibberish, releases its code and weights, and plugs into an existing generative workflow — while the consumer entry now lives on another platform.
-
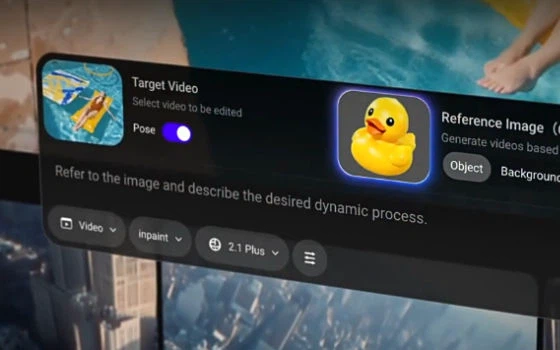
Tongyi Wanxiang makes thirty seconds of video with sound in one pass
The third generation produces up to thirty seconds of multi-shot footage with dialogue, music and effects in one generation, takes up to twenty multimodal references including documents and web pages, and lets the result be edited and extended.
-
Jimeng AI settles images, video and a canvas behind one entrance
Image generation, video generation and a canvas that keeps the result editable share one entrance, both the opening and closing frame can be pinned, and the workflow is built around Chinese prompts.
-
Recraft outputs editable SVG vector art instead of pixels
The vector variant writes editable SVG files rather than raster images, a handful of references can lock an entire brand style without training, and text length and placement stay under control.
-
Adobe Firefly puts licence safety ahead of spectacle
The in-house models are trained only on licensed and public-domain material, output without a beta label is cleared for commercial work, and generative fill lives inside Photoshop instead of beside it.
-
Flux folds generation and editing into one set of weights
The compact member of the second generation does text to image, single-reference editing and multi-reference composition with the same weights, opens fully for commercial use, and runs on a mid-range gaming card.
-
Invoke opens on a canvas, not on a prompt box
A self-hosted image workstation under Apache 2.0 where generation and retouching share one infinite canvas, layers can carry their own prompts, and a node graph waits behind the canvas for anyone who needs a process they can repeat.
-
Fooocus hides the sampler and leaves you a prompt box
Built entirely on SDXL with the sampling parameters tucked behind presets. A GPT-2 prompt engine runs offline to fill in the details, so one short sentence is enough to get four finished pictures.
-
SD WebUI Forge keeps the old interface and rebuilds what sits under it
Same tabs, same parameter column, same model folder. The rewriting went into memory tracking and model support, so a card that struggled before now finishes the same job in half the time.
-
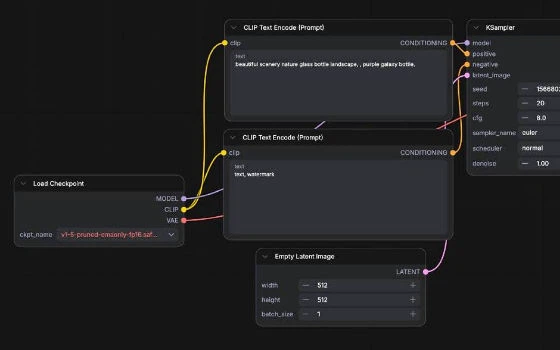
ComfyUI turns image generation into a diagram you can rewire
Every step becomes a box on an endless canvas, wired to the next. Save the graph as a file, drag a generated image back in to recover it, and run isolated environments so one bad node pack does not break the rest.
-
第 1 / 1 页