
-
Kolors writes Chinese characters correctly and opens code and weights
A text-to-image model that draws Chinese hanzi correctly instead of producing gibberish, releases its code and weights, and plugs into an existing generative workflow — while the consumer entry now lives on another platform.
-
Tongyi Wanxiang makes thirty seconds of video with sound in one pass
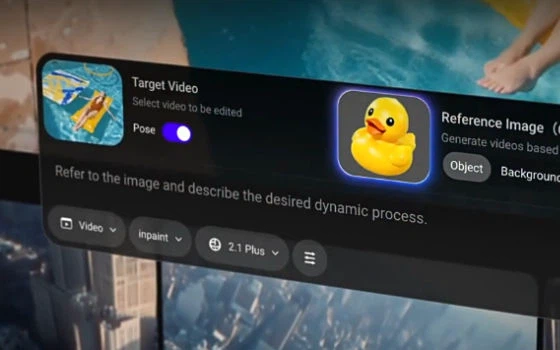
The third generation produces up to thirty seconds of multi-shot footage with dialogue, music and effects in one generation, takes up to twenty multimodal references including documents and web pages, and lets the result be edited and extended.
-
Jimeng AI settles images, video and a canvas behind one entrance
Image generation, video generation and a canvas that keeps the result editable share one entrance, both the opening and closing frame can be pinned, and the workflow is built around Chinese prompts.
-
Recraft outputs editable SVG vector art instead of pixels
The vector variant writes editable SVG files rather than raster images, a handful of references can lock an entire brand style without training, and text length and placement stay under control.
-
第 1 / 1 页