
-
Chatterfly: hold Fn, speak, and get a finished draft
A Tencent voice input tool in beta since September 2026: hold Fn, say it the way you would say it out loud, and get a cleaned up written version that already matches the audience you are writing for.
-
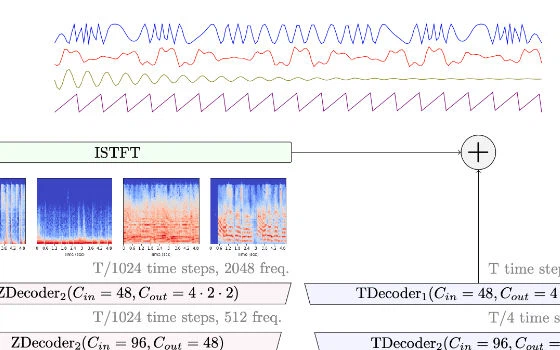
Demucs splits a mixed song into four stems from one command line
An open source source separation model that takes a mixed song apart into drums, bass, vocals and the remaining backing. It runs as one command line call, can be driven from Python, and the code is MIT licensed.
-
Ultimate Vocal Remover splits a track into voice and backing, with nothing to set up
An open source tool that pulls a song apart into vocals and accompaniment using source separation models. The official installer bundles the interface, Python, PyTorch and the dependencies, so nothing has to be prepared beforehand.
-
WhisperX puts word timestamps and speaker labels on top of Whisper
A pipeline that repairs two gaps in Whisper: timestamps stop at sentence level and there is no batch mode. WhisperX force aligns for word level timing, then labels speakers, and reports 70 times real time on the large-v2 model.
-
Buzz keeps transcription on your own machine, with Whisper underneath
A desktop tool that transcribes and translates audio on your own computer with Whisper underneath. It takes media files or links, records from a microphone in real time, labels speakers, and exports plain text alongside SRT and VTT subtitles.
-
Whisper ships in six sizes, and the memory budget decides which one
A general purpose speech recognition model that handles transcription, translation into English and language identification in one pass. Six sizes run from about 39 million to about 1.55 billion parameters, and code and weights are both MIT licensed.
-
F5-TTS hands you MIT code and non-commercial weights, installed with one pip line
An open source speech synthesis project built on flow matching, with a pip package, command line inference and a Gradio web interface. The code is MIT; the pretrained weights are non-commercial because of the training data.
-
CosyVoice covers 9 languages and 18 Chinese dialects, with zero-shot cloning on top
An open source speech synthesis model whose latest generation handles cross-lingual zero-shot cloning, 9 foreign languages and more than ten Chinese dialects and accents, released under the Apache 2.0 licence.
-
GPT-SoVITS fine-tunes a voice model on one minute of audio, five seconds for zero-shot
An open source speech synthesis WebUI. Five seconds of a human voice is enough for zero-shot output, one minute of training data is enough to fine-tune a closer timbre, and inference can cross five languages including Mandarin, English, Japanese, Korean and Cantonese.
-
第 1 / 1 页